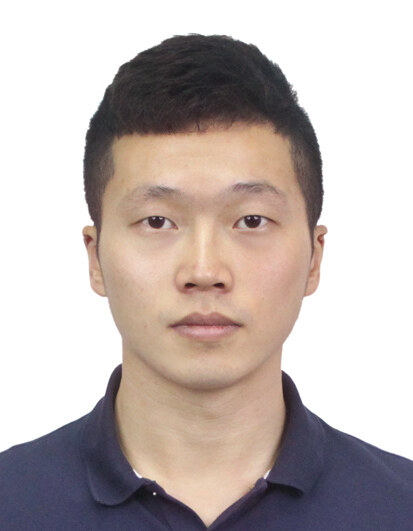
Yuxuan Zhou
LLM Pretraining · Multi-Token Prediction and Looped Architectures

About
I currently work on the pretraining of large language models. My work spans Multi-Token Prediction and Looped Architectures, as well as probabilistic modeling, e.g., scoring functions beyond softmax and speculative decoding, with first-authored papers at ICML, NeurIPS (Oral), CVPR, ACL and ICLR (Oral).
I was trained as an automotive engineer. I took part in the pre-development of the steering control system for the Audi A8 (2018 Edition), on the modeling and simulation of driving dynamics.
Languages: Mandarin Chinese (native) · English (fluent) · German (C1)
News
- 2026.10ECHO released.
- 2026.04HSD accepted to ICLR 2026 as an Oral.
- 2025.12MaxSup accepted to NeurIPS 2025 as an Oral.
- 2025.10Received Ph.D. from the University of Mannheim. Thesis:
New Frontiers in Neural Probabilistic Scoring
- 2025.07“Balancing Diversity and Risk in LLM Sampling” accepted to ACL 2025.
- 2024.07MultiMax accepted to ICML 2024.
- 2024.06BlockGCN accepted to CVPR 2024.

Adopted at Scale
A causal self-recursive Multi-Token Prediction (MTP) paradigm:
- Final-layer sharing: turns the indirect supervision of auxiliary MTP into direct multi-horizon supervision of the backbone, resulting in more substantial gains at a single prediction depth and continued gains with added depth, where auxiliary MTP saturates; the gains concentrate on reasoning and code in pretraining, with QA & multiple choice holding, and extend to both categories after supervised finetuning.
- Dynamic Depth Sampling: makes deep supervision affordable while preserving its gains.
- Emergent depth extrapolation: maintains high acceptance rates even when drafting beyond the trained depth, entirely eliminating the need for post-hoc drafters.
A learnable generalization of SoftMax for attention and output distributions:
- Sparse yet diverse: a unified SoftMax temperature can only trade off the sparsity and multi-modality of the generated distribution; MultiMax’s piece-wise temperature breaks this trade-off and pushes out the Pareto frontier, suppressing the long tail of implausible tokens while preserving the inherent diversity of plausible next tokens.
- Negligible cost: MultiMax modulates the logits element-wise inside the chunked, Triton-fused cross-entropy kernel, just before its SoftMax, costing merely around 1% training slowdown and no extra memory for a pretraining-loss gain above 0.01.
Experience
ERNIE Team, Baidu — Staff Research Engineer
Apr 2026 – Present
Multi-Token Prediction and looped architectures.
Dexmal — Research Intern
Oct 2025 – Jan 2026
Self-evolving diffusion policy for long-horizon robot manipulation (SeedPolicy).
Qwen Team, Alibaba — Research Intern
Jan 2025 – Apr 2025
Lossless verification for speculative decoding (HSD, ICLR 2026 Oral).
Language Technologies Institute, CMU — Visiting Researcher
Jun 2023 – Oct 2023
Topology-aware graph networks for action recognition (BlockGCN, CVPR 2024).
Tongyi Lab, Alibaba — Research Intern
Jul 2022 – Jul 2023
Spatial priors for vision transformers (SP-ViT, BMVC 2022).
Bosch Center for Artificial Intelligence — Research Intern
Jan 2019 – May 2019
Unsupervised anomaly detection for deep generative models, applied to optical inspection on assembly lines (NeurIPS 2020).
Chassis Electronics, Audi AG — Research Intern
Apr 2017 – Oct 2017
Dynamics modeling and simulation of the steering control system for the Audi A8
(2018 Edition), including a non-Newtonian fitting model of the tire's nonlinear
force–slip characteristics.
Education
Ph.D. in Computer Science — University of Mannheim
2020 – 2025
Advised by
Margret Keuper and
Mario Fritz.
Research focus: Transformers, Multi-Token Prediction and Speculative Decoding.
M.Sc. in Automotive Engineering — University of Stuttgart
2015 – 2018
Research focus: physical modeling of driving dynamics and internal combustion engines.
B.Sc. in Automotive Engineering — Tongji University
2010 – 2015
Foundations of automotive engineering; a mandatory extra year of German language study.
Selected Publications
- ECHO: Efficient Causal Self-Recursion Beyond Auxiliary Multi-Token Prediction. arXiv 2026 · arXiv · code · first author
- Lossless Hierarchical Speculative Decoding. ICLR 2026 (Oral) · arXiv · code · first author
- MultiMax: Sparse and Multi-Modal Attention Learning. ICML 2024 · arXiv · code · first author
- MaxSup: Overcoming Representation Collapse in Label Smoothing. NeurIPS 2025 (Oral) · arXiv · code · first author
- Balancing Diversity and Risk in LLM Sampling. ACL 2025 · arXiv · code · first author
- BlockGCN: Redefine Topology Awareness for Skeleton-Based Action Recognition. CVPR 2024 · paper · code · first author
- SP-ViT: Learning 2D Spatial Priors for Vision Transformers. BMVC 2022 · arXiv · code · first author
- SeedPolicy: Horizon Scaling via Self-Evolving Diffusion Policy for Robot Manipulation. arXiv 2026 · arXiv · code · co-first author
- Understanding Anomaly Detection with Deep Invertible Networks through Hierarchies of Distributions and Features. NeurIPS 2020 · arXiv · code · second author
Views: – today · – total
© Yuxuan Zhou 2026 · Last updated Oct 2026